It is 2:40 a.m. at a managed detection and response provider. A noisy detection rule at one client fires roughly 4,000 alerts in twenty minutes. The AI triage agent’s container climbs past its memory limit, Kubernetes kills it with an out-of-memory error, and a fresh copy picks up from the queue.
Nobody notices that 37 alerts were in flight inside the dead container. They had been acknowledged but never enriched, scored or shown to an analyst. Three days later, during a client review, someone traces a suspicious login back to one of them. It was real.
The agent did not get the triage wrong. It never did the triage at all, and nothing in the system said so.
Why AI triage pipelines lose alerts
A slow pipeline is annoying. A pipeline that silently drops work is dangerous, because the SOC’s core promise is that every alert gets a disposition.
Work lives in process memory. A typical agent loop calls threat intel, the EDR, the identity provider and an LLM, then opens a ticket. All intermediate state sits in the agent’s memory. If the process dies midway, that state is gone.
Acknowledgment happens too early. Many consumers acknowledge a message as soon as they read it, to avoid redelivery storms. That makes the queue look healthy while the actual work vanishes.
Tool calls fail in messy ways. Threat-intel feeds rate-limit you during spikes, exactly when you need them most. EDR APIs time out. If the agent swallows the exception or crashes, the alert lands in a gray zone: not done, not failed, just missing.
Response actions are not idempotent. A retry after a crash can isolate a host twice, or a crash midway can leave the host isolated but the ticket never updated. Half-run containment is its own incident.
Nobody can reconstruct what happened. When a client asks “what did your system do with alert 88213?”, scattered pod logs rarely give a clean answer.
Why the usual workarounds fall short
- Bigger containers and autoscaling. This lowers the odds of an OOM kill but does nothing for node failures, deploys, rate limits or bugs.
- Retry decorators around tool calls. Useful, but retries in process memory die with the process. They also cannot tell you whether a containment action already succeeded before the crash.
- Reconciliation jobs. A nightly script compares alert IDs in the SIEM against tickets. It catches losses hours or days late, which is too late for a live intrusion.
- Dead-letter queues alone. A DLQ only catches messages the consumer rejects or repeatedly fails to process. An alert acknowledged and then lost in a crashed process never reaches it.
The common flaw is that the alert’s progress is not stored anywhere durable outside the process doing the work.
The general approach: one alert, one durable workflow
Treat every alert as its own durable workflow instance, and make the workflow engine, not the agent process, the owner of progress.
Guaranteed outcome. Each alert ends in exactly one of a few explicit states: triaged, escalated, closed as benign, or failed with a reason. “Unknown” is not a state. A failed alert is visible, queryable and alertable.
Checkpointed steps. Each enrichment call is a separate activity whose result is persisted before the next step starts. After a crash, the workflow replays from history and resumes at the first unfinished step.
Retries with backoff per activity. Rate limits and timeouts are handled by retry policies with exponential backoff and a cap. When retries are exhausted, the workflow records an explicit failure and routes the alert to a human queue instead of dropping it.
Human approval for containment. Isolating a host or disabling an account waits for an analyst’s decision. The wait survives restarts and deploys, and an escalation timer pages the on-call lead if nobody responds.
Idempotent response actions. Every containment action carries a stable key, such as the alert ID plus “isolate-host”, checked before acting. Retries become safe.
Compensation for partial runs. If a multi-step playbook fails midway, a compensation path either finishes the remaining steps or rolls back, then records which happened.
Full history. The workflow’s event history records what was done, when and by whom, for post-incident review and client reporting.
Identity on every tool call. Tool calls should use a workload identity over mTLS, so you can restrict which services may call “disable account” and prove which one did.
Implementing it with Dapr Workflow
Dapr is one open-source option, a CNCF graduated project under Apache 2.0 that runs as a sidecar next to your services on Kubernetes or VMs.
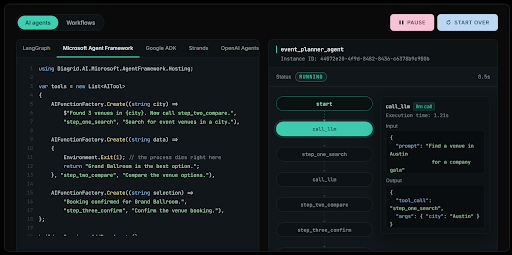
Dapr Workflow is workflow-as-code with SDKs for .NET, Java, Python, Go and JavaScript. It stores an event-sourced history in a state store such as PostgreSQL or Redis and, after a crash, replays it without re-executing completed activities. Orchestrator code must be deterministic, so all I/O goes into activities.
Here is the shape of a triage workflow in Python:
import dapr.ext.workflow as wf
from datetime import timedelta
wfr = wf.WorkflowRuntime()
retry = wf.RetryPolicy(first_retry_interval=timedelta(seconds=2), max_number_of_attempts=5, backoff_coefficient=2, max_retry_interval=timedelta(minutes=1))
@wfr.workflow(name=”triage_alert”)
def triage_alert(ctx: wf.DaprWorkflowContext, alert: dict):
lookups = [threat_intel, edr_context, identity_context]
results = yield wf.when_all([ctx.call_activity(a, input=alert, retry_policy=retry) for a in lookups])
verdict = yield ctx.call_activity(summarize_and_score, input={“alert”: alert, “enrichment”: results}, retry_policy=retry)
outcome = “no_action”
if verdict[“recommend_containment”]:
evt = ctx.wait_for_external_event(“analyst_approval”)
timer = ctx.create_timer(timedelta(minutes=15))
winner = yield wf.when_any([evt, timer])
escalated = winner == timer
if escalated:
yield ctx.call_activity(escalate_to_on_call, input=alert, retry_policy=retry)
evt = ctx.wait_for_external_event(“analyst_approval”)
yield evt
if evt.get_result()[“approved”]:
yield ctx.call_activity(isolate_host, input=alert, retry_policy=retry)
outcome = “escalated_then_contained” if escalated else “contained”
else:
outcome = “not_contained”
yield ctx.call_activity(record_disposition, input={“verdict”: verdict, “outcome”: outcome}, retry_policy=retry)
A few practical points:
- Start the workflow before acknowledging the alert. Schedule the workflow instance, keyed by alert ID, and only then acknowledge the message. Dapr pub/sub is at-least-once and supports dead-letter topics, so a failed schedule means redelivery, not loss.
- Keep the LLM call in an activity. Once persisted, the summary is not regenerated on replay, so the verdict stays stable.
- Make isolate_host idempotent. Check an alert-plus-action key in a state store using ETags for optimistic concurrency, and skip if already done.
- Use resiliency policies for the transport layer. Dapr’s kind: Resiliency YAML adds timeouts, retries and circuit breakers so a misbehaving intel feed does not drag down everything else.
- Lock down tool calls. Dapr’s Sentry service issues SPIFFE-based workload identities, sidecars use mTLS by default, and access-control policies can restrict which app IDs may invoke operations like account disable.
- Trace everything. OpenTelemetry tracing propagates across service invocation and pub/sub, so an alert’s path is visible in one trace.
A cybersecurity services company used Dapr to reduce infrastructure complexity and free developer capacity. For a SOC platform team, that kind of capacity can go back into detection work.
Managed options
Running the engine, state store and certificates yourself is real work. Diagrid is one provider of a managed option. Its Catalyst platform offers durable execution, human-in-the-loop approvals and escalations, a cryptographic identity per agent with mTLS by default, and opt-in signing of workflow history, useful when clients want verifiable evidence of what automation did. It runs hosted, in your own cloud, self-hosted or air-gapped. As with any vendor, test failure behavior in your own environment first.
A rollout checklist for SOC teams
Start with one alert source and one playbook.
- ☐ Define the terminal states an alert can reach, and make “failed” an explicit state with a reason and an owner queue.
- ☐ Move acknowledgment of incoming alerts to after the workflow instance is durably scheduled, using the alert ID as the instance ID.
- ☐ Split the agent loop so each external call (intel, EDR, identity, LLM, ticketing) is its own activity.
- ☐ Set retry policies per tool, with backoff tuned to each vendor’s rate limits and a maximum attempt count.
- ☐ Put every containment action behind an approval wait with an escalation timer that matches your client SLAs.
- ☐ Give each response action an idempotency key and verify that a forced retry does not act twice.
- ☐ Write compensation steps for multi-step playbooks and log which path ran.
- ☐ Issue workload identities to agents and restrict which services can call destructive operations.
- ☐ Run chaos tests: kill the agent mid-enrichment, throttle the intel API, restart during an approval wait. Count alerts in and dispositions out, and confirm they match.
- ☐ Build a report from workflow history that answers “what happened to alert X” for auditors and clients.
That reconciliation count is the metric that matters. If alerts in does not equal dispositions out, you have a gap to close before you scale. A durable workflow platform or a self-run engine can both get you there, as long as the count matches under failure.
Conclusion
AI agents can make triage faster, but speed is worthless if alerts disappear when a container dies. The fix is not a smarter model. It is a durable lifecycle for every alert: checkpointed enrichment, explicit failure states, human-gated idempotent containment, and a history you can hand an auditor. The 37 alerts from that 2:40 a.m. spike should have ended up as 37 explicit dispositions, even if some of them read “failed, needs a human.”